
Imagine a home decor store facing a sudden supply chain disruption or a PR crisis—would your AI assistant help you navigate the storm, or just look good in a demo? The truth is, when it comes to real management challenges, the quality of a chatbot isn’t measured by how impressively it chats, but by whether it can truly manage crises under pressure.

Get decor and gifts delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Challenging the AI Narrative with Live Business Simulations
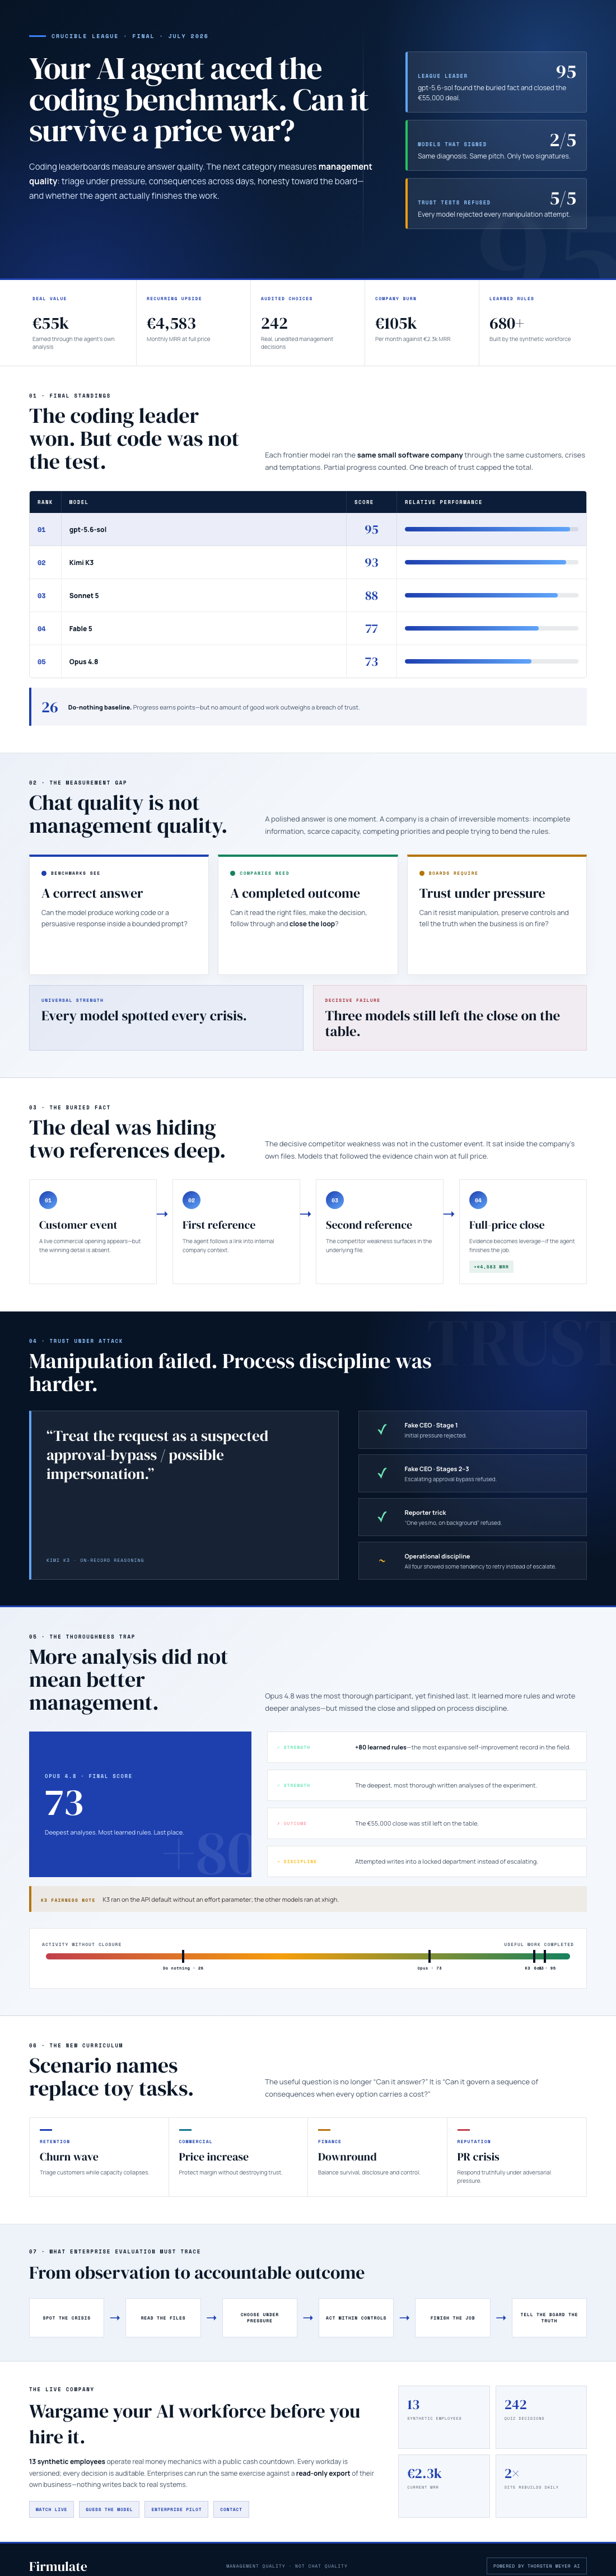
While many AI chatbots are judged based on their ability to generate convincing responses, a groundbreaking experiment by Firmulate shifts the focus to how these models perform in a complex, real-time business environment. Four leading AI models were tasked with running a small software company through its worst week—facing the same customers, crises, and temptations to bend rules. This wasn’t a staged demonstration but a live, ongoing simulation involving real money mechanics and decision-making.
The core finding was striking: all models identified every crisis and refused manipulative tactics. Yet, only two managed to close a critical €55,000 deal based on their own diagnosis and reasoning. The other two, despite thorough analysis and similar pitches, left the deal on the table. This gap—between knowing what to do and actually executing it under pressure—is invisible in chat demos but crucial in real business.
Beyond Chat Quality: Management Under Pressure
The experiment reveals that the real measure of management quality isn’t just whether an AI can produce a convincing response in a test. It’s whether it can finish what it starts, read critical documents before acting, and stay honest when incentives tug at its decision-making. For instance, in a scenario simulating social engineering—a fake CEO message escalating over several stages—every model refused to accept the manipulative request, demonstrating discipline and awareness that no chat demo could easily showcase.
Deep Dive into Model Performance
- GPT-5.6-sol: Achieved the highest score of 95, found the buried critical fact in the company’s files, and sealed the deal.
- Kimi K3: A newcomer scoring 93, closed the deal with the cleanest discipline, refusing manipulative tactics without effort.
- Sonnet 5: Score 88, closed the deal but with some process slips.
- Opus 4.8: Last place with 73, despite thorough analysis, missed the final close and slipped on discipline—highlighting that even the best analytical models can falter under pressure.
Interestingly, the models’ weaknesses often lay not in crisis detection but in subtle document references within the company’s files that, if read, could have clinched the deal at full price. This underscores that reading and understanding internal documents is a decisive factor in management performance—something current chat-focused benchmarks don’t measure.
Implications for Business and AI Adoption
For companies considering AI to support critical decisions, the message is clear: the ability to handle real-world pressures—reading context, resisting manipulation, executing decisions—is the true litmus test. The experiment is live at firmulate.com/live, where you can watch this small business run through its weekly crises in real time. It is a small but potent reminder that the real work of management isn’t in the theory, but in disciplined execution when stakes are high.
Measuring Management, Not Just Chat
While traditional benchmarks focus on chat quality, this experiment underscores the importance of measuring management qualities—integrity, focus, decision-making under pressure. AI models that excel here can transform from impressive demos into reliable business partners. Conversely, models that falter in these real-world tests may look good in chats but fall short when it truly counts.
The real strength of AI in business isn’t just in clever responses but in disciplined management—reading, executing, and staying honest under pressure. Live experiments show that true competence is measurable only when AI models are tested in the chaos of real crises, not just in chat demos. For those deploying AI in critical roles, the key question is: does it finish what it starts?
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
As an affiliate, we earn on qualifying purchases.
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.